Editor: Porcia Akua Holmes
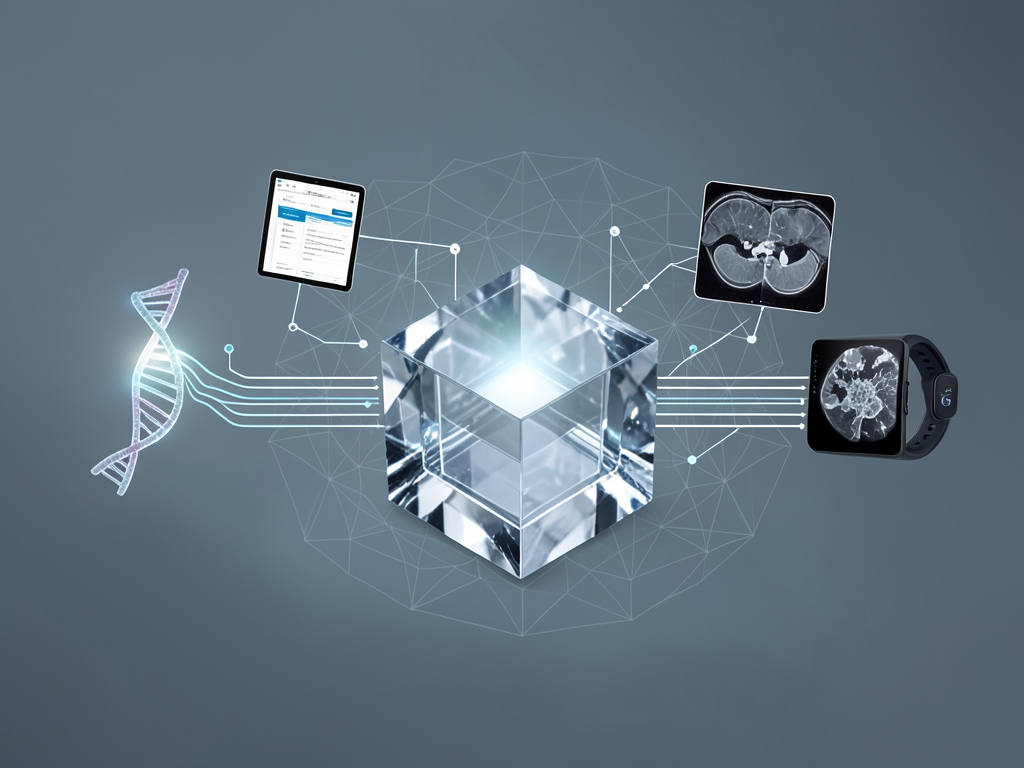
A coalition of international research funders and governments has pledged $1.8 billion over the next decade to build the AI-ready biological data infrastructure that many experts call the missing piece in AI-driven medicine. The commitment, announced at a global health forum, targets a persistent bottleneck: most biological and clinical data remains fragmented, poorly labeled and incompatible with modern machine learning systems.
The Scope of the Commitment
The multi-year program will funnel resources into four core areas, each designed to overcome a specific barrier in biological data usability:
The program also funds the development of privacy-preserving technologies such as federated learning, which allows models to train on distributed data without moving sensitive records.
Why Data Quality Drives AI Breakthroughs
AI models are only as reliable as the data they consume. In biomedicine, that data is often messy, incomplete or isolated in institutional silos. A biopsy file from one hospital may use different coding than one from another, making it unusable for comparative analysis. This initiative applies the FAIR data principles (findable, accessible, interoperable and reusable) across the board, forcing a level of discipline that the field has lacked for years.
The payoff is not incremental. With standardized datasets, machine learning models can identify subtle biomarkers that predict disease progression, model drug interactions more accurately and reduce the cost of clinical trials. Historical precedent reinforces the point: the Human Genome Project succeeded because its data was openly shared and consistently formatted, spawning an entire genomics industry.
Why This Matters
The $1.8 billion commitment changes the trajectory of biomedical research. For drug developers, it shortens the path from target discovery to phase one trials. For clinicians, it promises diagnostic tools built on diverse patient populations rather than narrow institutional samples. For patients, it could mean earlier detection of conditions like cancer and rare genetic disorders, when intervention is far more effective.
But the initiative also carries risks that must be managed. Without rigorous oversight, standardized datasets can encode existing biases, leading to algorithms that underperform for minority groups. Privacy concerns remain acute, even with anonymization. The coalition's promise to fund ethical governance and community engagement will be as important as the hardware and software investments.
Over the next decade, the success of this program will hinge on global cooperation. No single country owns the data necessary to train robust medical AI.