Senior Editor: Alan Agbele
When AlphaGo played Move 37 against Lee Sedol in 2016, the move looked like a mistake. It was not. That moment revealed a kind of machine reasoning that today's large language models still cannot replicate. The difference matters deeply for fields like medicine, engineering and scientific research.
The AlphaGo Blueprint
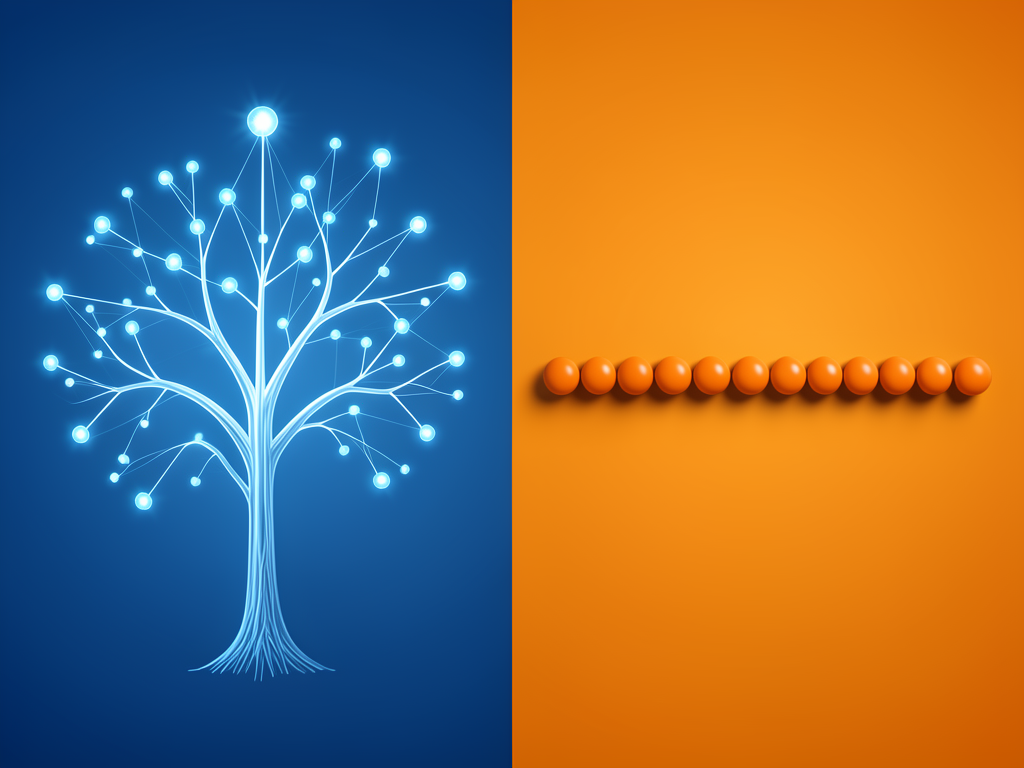
AlphaGo's architecture offered a striking analogue of Daniel Kahneman's two-system model of thought. Its policy network supplied fast, intuitive guesses about strong moves. Its search machinery then tested those hunches by explicitly constructing and exploring a game tree with thousands of branches. Each branch represented a different possible future. This combination let AlphaGo invent moves no human had considered. Lee, after the match, acknowledged that AlphaGo appeared creative, not merely probabilistic.
But that creativity came from reasoning, not intuition alone. The search process maintained a record of what the system knew and how it reached conclusions. That record, the game tree, allowed inspection of the evidence and assumptions behind each choice. This is the kind of transparency that scientists and doctors demand from AI systems.
Why LLMs Fall Short
Large language models work by predicting the next token, over and over. That is System 1 in action: fast, associative and surprisingly fluent. The introduction of chain-of-thought reasoning seemed to add deliberation, but it did not introduce a genuinely separate reasoning mechanism. The intermediate steps are still produced by the same next-token prediction process, iterated longer before the model commits.
This is a problem because in high-stakes applications, the process matters as much as the outcome. A medical diagnosis system that cannot show its reasoning leaves clinicians unable to verify or challenge its conclusions.
Why This Matters
The limitations of current LLMs have direct consequences. Scientists who rely on AI to generate hypotheses need to trace how the system arrived at a novel idea. Engineers using AI to design materials must be able to identify flawed assumptions when a design fails. Without a genuine reasoning architecture, these models will remain unreliable partners in discovery.
The lesson from AlphaGo is clear: True machine reasoning requires a separation between intuition and deliberate, inspectable search. The field needs a fresh approach, drawing on AlphaGo's architecture rather than scaling up pattern matching. Researchers who believe the path forward lies in equipping AI with explicit, revisable belief states are already exploring new directions. This is the challenge that will define the next generation of artificial intelligence.