Editor: Porcia Akua Holmes
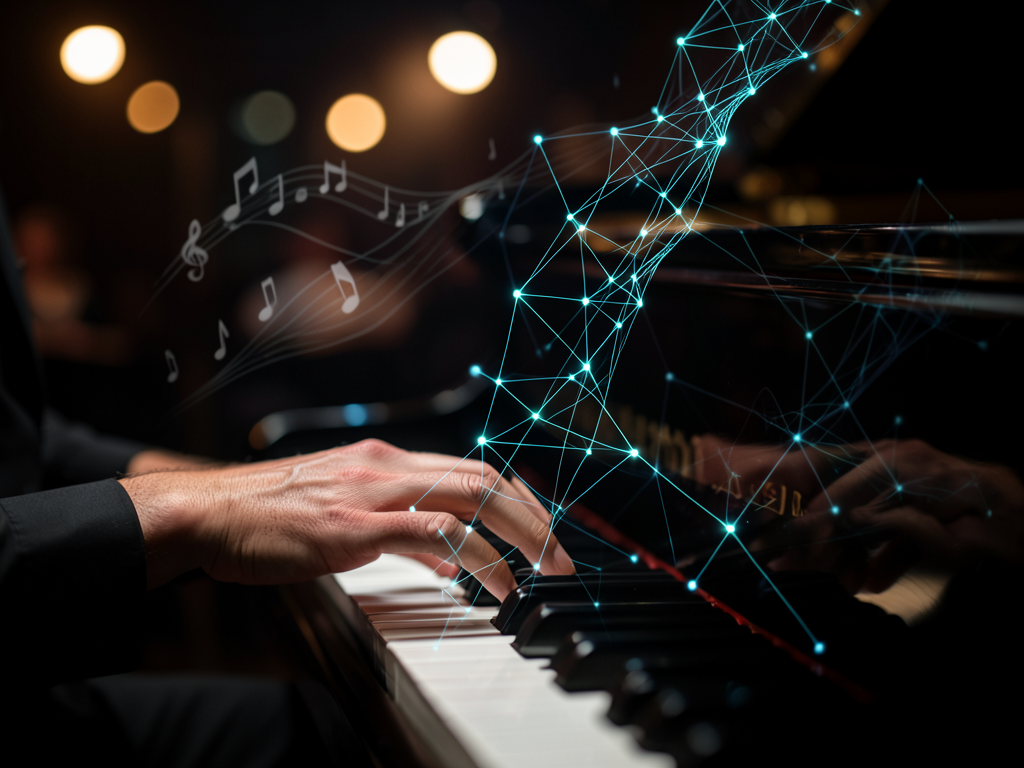
Researchers have developed a new artificial intelligence technique that can learn the improvisational style of a jazz pianist. The method, called Learning Jazz Pianist Style, relies on cross-attention conditioning to analyze and replicate the nuanced phrasing and timing that define jazz piano. The approach marks a significant step in creative AI, moving beyond simple note prediction toward capturing musical expression.
How Cross-Attention Conditioning Captures Jazz Style
Traditional music generation models treat notes as individual events. The new method instead uses an attention mechanism that weighs the importance of each note in relation to others over time. Cross-attention conditioning lets the model align its internal representation with a target style profile, learning patterns such as syncopation, chord voicing and rubato. The system is trained on a dataset of recorded jazz piano performances and can generate new phrases that match the style of a specific musician.
Key aspects of the technique include:
Why This Matters
The method shifts AI music generation from simple note prediction to style transfer. Musicians and composers could use this tool to generate accompaniment that matches a specific player's feel, or to explore new stylistic combinations. For the AI research community, Learning Jazz Pianist Style demonstrates how attention mechanisms can capture subjective qualities like expressive timing. This opens the door to applying similar conditioning techniques to other art forms such as painting or dance, where subtle stylistic elements are hard to quantify.
Broader Implications for Creative AI
The technique could influence how AI interacts with human artists. Instead of replacing musicians, models that understand style can become collaborative tools. The focus on cross-attention conditioning suggests that future creative AI systems will prioritize context and intent over raw data generation. Early demonstrations show the model can improvise in real time when given a harmonic framework, hinting at applications in live performance software. However the approach currently requires significant computational resources for training, which may limit accessibility in the near term.