Editor: Porcia Akua Holmes
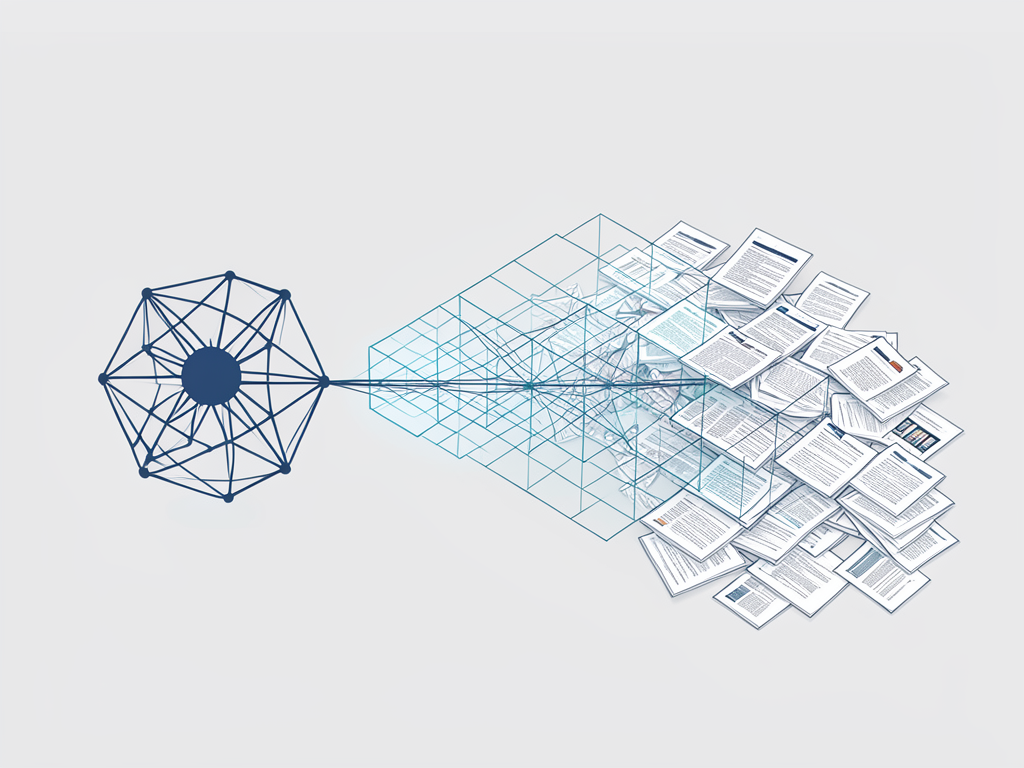
Enterprise AI is often portrayed as a technology racing to catch up with human reasoning but the real bottleneck has little to do with model intelligence. The systems that promise to automate decisions are starved of the very context that makes those decisions meaningful. Enterprises, however, already possess the cure. Decades of contracts, claims, case notes and internal policies sit unused inside their own systems, forming a business memory that most AI never touches.
The Unstructured Data Opportunity
Industry research has long flagged unstructured content as an untapped resource. Emails, PDFs, images, meeting transcripts and legacy databases all contain the decisions and rationale that define how a company operates. This is the accumulated judgment that separates a general-purpose LLM from an organization's unique perspective. The challenge is that this information is fragmented, poorly labeled and often locked inside silos that AI cannot reach.
A context layer changes that dynamic. It acts as a filter that determines which data AI may access, whether that data is current and authorized, and how it relates to the task at hand. When built correctly, this layer transforms raw files into governed, traceable knowledge. The result is not perfect recall but relevant and reliable context.
Ontologies: The Missing Map
Having data available is insufficient. AI needs to understand how the pieces fit together, and that is where ontologies come in. An ontology is a formal framework that defines the entities, relationships and rules within a business. It tells the AI that a "physician note" links to a "diagnosis" and a "treatment plan," or that a "compliance policy" governs a "transaction."
This is especially critical in regulated sectors. In healthcare, ontologies connect lab results to patient records and billing codes. In financial services, they map regulatory requirements to internal controls. Without this structure, AI may retrieve documents but fail to grasp their significance, leading to outputs that look plausible yet miss the mark.
- Define a clear use case: Start with one high-value problem and gather the authoritative content it requires.
- Preserve access controls: Ensure that the AI operates within the same permission boundaries as human employees.
- Enrich with metadata: Add tags, relationships and validity dates to make content machine-interpretable.
- Test outputs rigorously: Verify accuracy, traceability and usefulness before expanding automation to other areas.
Why This Matters
The stakes go beyond convenience. Enterprise AI that lacks business memory is both inefficient and risky. Inefficient because it generates generic answers that require heavy human review. Risky because it can act on stale, unrelated or unauthorized information, producing compliance failures in industries where errors carry heavy penalties. Building a context layer now means enterprises can scale agentic automation with confidence, using AI to handle routine decisions while humans oversee exceptions. The longer organizations ignore their unstructured data, the more they will pay for models that cannot see what they already know. This is the competitive edge that separates AI leaders from laggards.
From Fragments to Working Memory
Business memory is not about storing everything. It is about connecting the right pieces of context to the right decision at the right time. And it is achievable without replacing existing systems. By investing in infrastructure that ingests unstructured content, applies ontologies and enforces governance, enterprises can turn dormant files into active intelligence. The answer to the memory problem was always inside the organization. The task is to make it accessible.